CS-503 (A) · Data Analytics/Unsolved PYQ Paper
CS-503-A Data Analytics - Nov 2023 Question Paper
Under each question, How to answer lists the points an answer should cover, outlined by CampusPrep from the syllabus. Check the details against your textbook.
-
7 MarksaSuppose the weights of 800 male students are normally distributed with 28.8 kg and SD of 2.06 kg. Find the number of students whose weights are
- i)Between 28.4 kg and 30.4 kg
- ii)More than 31.3 kg
How to answer
- State mean = 28.8 kg, SD = 2.06 kg, N = 800 and normal distribution assumption
- Convert limits to Z-scores using $Z=(X-\mu)/\sigma$
- Find areas from normal table for i) between 28.4 and 30.4 and ii) >31.3
- Multiply probabilities by 800 to get number of students
-
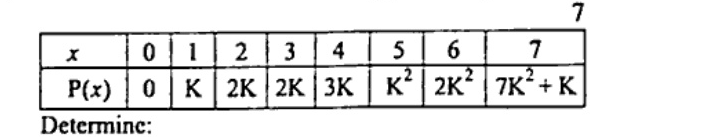
7 MarksbA random variable has the following probability function: Determine:
- i)k
- ii)mean
- iii)variance
How to answer
- Use $\sum P(x)=1$ to form equation in K and solve quadratic, reject negative value
- Compute mean as $E[X]=\sum xP(x)$
- Compute $E[X^2]=\sum x^2P(x)$
- Compute variance as $Var(X)=E[X^2]-(E[X])^2$
-
7 MarksaA sales tax officer has reported that the average sales of the 500 businesses that he has to deal with during a year is Rs. 36,000 with a standard deviation of Rs. 10,000. Assuming that the sales in these businesses are normally distributed, find:
- i)The number of business as the sales of which are greater than Rs. 40,000.
- ii)The percentage of business the sales of which are likely to range between Rs. 30,000 and Rs. 40,000.
How to answer
- State mean Rs. 36,000, SD Rs. 10,000, N=500, normal distribution
- Compute Z for 40,000 and 30,000
- Find tail area >40,000 and multiply by 500 for count
- Find area between 30,000 and 40,000 for percentage
-
7 MarksbDiscuss the trends in big data generation and acquisition.
How to answer
- Define big data generation sources and acquisition concept
- Discuss trends: IoT, social media, mobile, machine-generated data growth
- Discuss acquisition trends: real-time ingestion, sensors, cloud, streaming
- Conclude with volume-velocity-variety implications
-
14 MarksExplain the following:
- a)Predictive analytics
- b)Inter-and Trans-firewall analytics
- c)Information management
- d)Crowd sourcing analytics
How to answer
- Define each of the four analytics terms
- Explain purpose and key techniques for each
- Give one example/application for each
- Compare relevance to data analytics
-
7 MarksaWith an example, explain the term social media analytics.
How to answer
- Define social media analytics and its need
- Describe data sources and metrics (sentiment, engagement)
- Give example e.g., brand monitoring / election prediction
- Mention tools and outcome
-
7 MarksbWhat are the various stages in big data analytics life cycle? Illustrate with a figure, explaining each of them.
How to answer
- List stages of big data analytics life cycle (discovery, ingestion, processing, analysis, visualization)
- Draw labelled life-cycle figure
- Explain each stage briefly
- Mention iteration and deployment
-
7 MarksaBrief about the main component of Map Reduce.
How to answer
- Define MapReduce paradigm
- Describe Map, Shuffle/Sort, Reduce phases
- Mention JobTracker/TaskTracker or main components
- Give data flow example
-
7 MarksbWhat is Hadoop? Describe the role of Hadoop in big data analysis. Also explain core components of Hadoop.
How to answer
- Define Hadoop and its origin
- Explain role in storage and processing of big data
- Describe core components: HDFS, YARN, MapReduce (and common utilities)
- Mention scalability and fault tolerance benefits
-
7 MarksaDescribe the structure of HDFS in a Hadoop ecosystem using a diagram.
How to answer
- Define HDFS and its design goals
- Draw HDFS architecture with NameNode, DataNodes, blocks
- Explain replication, read/write flow
- Mention rack awareness and fault tolerance
-
7 MarksbWhy is finding similar items important in Big Data? Illustrate using two example applications.
How to answer
- Define similar-items problem (near-duplicates, similarity measures)
- Explain importance: deduplication, recommendation, search
- Illustrate with two applications e.g., plagiarism / product recommendation
- Mention shingling / Jaccard / LSH briefly
-
7 MarksaWhy to choose Hadoop for processing Big Data in detail and explain the concept of distributed and parallel computing challenges?
How to answer
- List reasons: scalability, fault tolerance, commodity hardware, open source
- Explain distributed vs parallel computing challenges
- Relate Hadoop HDFS/MapReduce to those challenges
- Conclude with use cases
-
7 MarksbExplain in detail the interacting process with Hadoop Ecosystem. List out various big data processing technologies.
How to answer
- Describe Hadoop ecosystem components (Hive, Pig, HBase, Spark, etc.)
- Explain interaction/workflow with HDFS/YARN
- List big data processing technologies
- Mention batch vs real-time processing
-
7 MarksaExplain Pig Data Model in detail and discuss how it will help for effective data flow?
How to answer
- Define Pig and its data model: Atom, Tuple, Bag, Map
- Explain Pig Latin flow and schema flexibility
- Discuss how it simplifies ETL/data flow
- Give example of data flow operation
-
7 MarksbDraw and explain architecture of APACHE HIVE. Explain various data insertion techniques in HIVE with example.
How to answer
- Draw labelled APACHE HIVE architecture (driver, metastore, execution engine)
- Explain query compilation and execution flow
- Describe data insertion techniques: LOAD, INSERT, partitioning with examples
- Mention HiveQL example
Go to where you left off?
Quick Add to Notes
Save questions, your own notes and screenshots into notes filed by unit. It takes a free account.
Create free accountHave an account? Log in
Notes Panel